 Nexus Tech Trends • • 1,495 words • 8 min read
The Selective Hearing Era: How AI Earbuds Filter Reality
Moving beyond basic ANC, neural audio models let you selectively mute the world or boost specific voices. Meet the future of acoustic augmented reality.
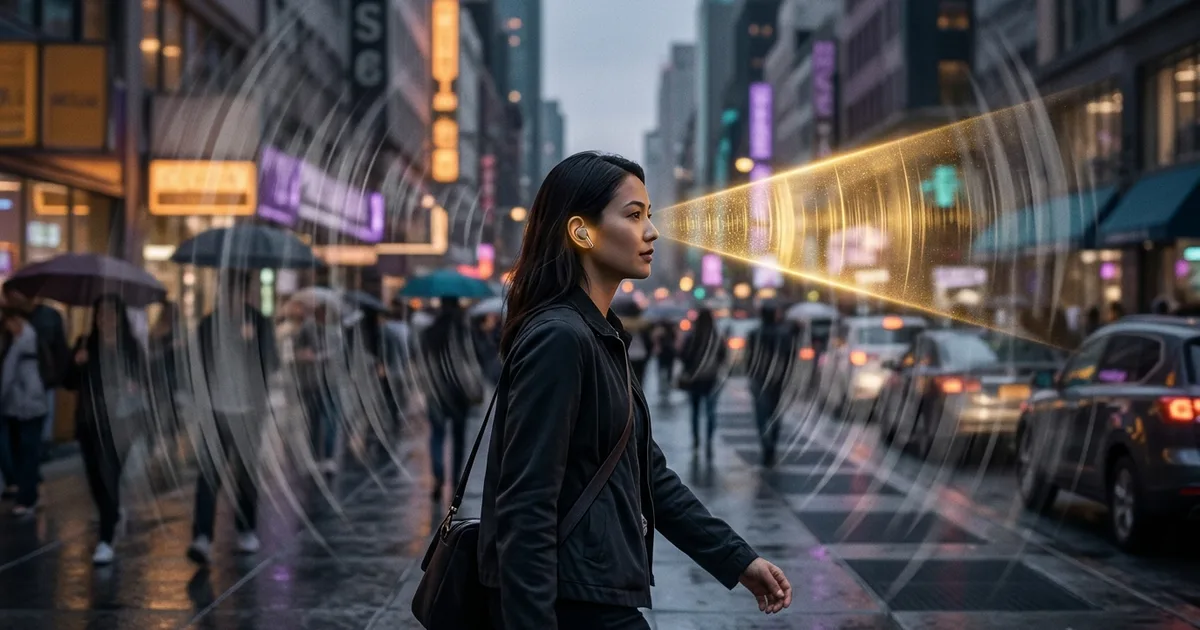
TL;DR (Direct Answer): Traditional noise cancellation blocks out the world with blanket anti-sound waves, often silencing voices you actually want to hear. Next-generation AI earbuds use lightweight, on-device neural networks to separate distinct sound sources in real time. Instead of an all-or-nothing mute switch, this technology lets you amplify your conversation partner, hush background babble, and keep critical sirens audible. It marks the shift from simple noise cancellation to true acoustic augmented reality.
The Cocktail Party Problem: Where Traditional ANC Hits a Wall
Imagine trying to read a book while twenty people shine flashlights of different colors into your eyes. That is what a noisy restaurant feels like to your ears.
Acousticians call this the cocktail party problem: the challenge of focusing on a single human voice amid a chaotic soup of competing conversations, clinking glasses, and background music. The human brain handles this using spatial hearing and visual cues, but consumer electronics have long struggled with it.
Traditional Active Noise Cancellation (ANC)—the technology that uses tiny microphones to record outside noise and inject an inverted sound wave into your ear to cancel it—is a blunt instrument. It excels at steady, predictable drones like airplane engines or air conditioner hums.
However, speech is chaotic and constantly changes in pitch and rhythm. Classic ANC cannot distinguish between a screaming child, an approaching delivery bike, or your friend sitting across the table. It either muffs everything or turns on a "transparency mode" that floods your ears with all ambient noise at once. To dig deeper into how modern micro-models tackle these complex sensory tasks, explore our tools on the AI Playground.
Under the Hood: How Neural Models Separate Reality
To selectively filter the world, hearables—smart in-ear devices packed with sensors and computing chips—must do something once thought impossible in miniature hardware. They must unbake the cake.
[MEMS Microphones] ──> [Low-Latency DSP] ──> [Neural NPU / Separation Model] ──> [Targeted Audio to Ear]
         │                                                    │
         └───────────── Direction & Target Profile ───────────┘
This streamlined hardware pipeline captures raw sound, isolates selected audio signatures via neural weights, and reconstructs the output stream in real time.
The process begins with Micro-Electro-Mechanical Systems (MEMS) microphones, which are microscopic acoustic sensors etched directly into silicon chips. These microphones capture surrounding air pressure changes and feed raw digital audio to a Digital Signal Processor (DSP), a chip specialized for rapid audio mathematics.
Next, on-device neural separation networks (such as scaled-down variants of VoiceFilter or Demucs) step in. Rather than merely adjusting volume knobs for high or low frequencies, the neural network analyzes the acoustic texture of every incoming sound:
- Spectral Extraction: The algorithm converts audio waves into visual-like frequency maps called spectrograms.
- Feature Matching: The model identifies distinctive voiceprints, isolating fundamental pitch, cadence, and vocal harmonics.
- Mask Generation: It creates a mathematical mask that isolates the desired speaker while attenuating competing sounds.
- Waveform Synthesis: The cleaned signal is converted back into an analog sound wave and played through the speaker driver.
Because these models run directly on micro-NPUs (Neural Processing Units) embedded in the earbud, no audio ever leaves your ear to travel to a cloud server.
Passive Isolation vs. Classic ANC vs. Semantic Hearing
Noise management has evolved across three distinct technological eras:
| Feature | Passive Isolation | Classic Active Noise Cancellation (ANC) | Semantic (Selective) Hearing |
|---|---|---|---|
| Primary Mechanism | Dense physical barrier (silicone tips or foam cups) | Phase-inverted sound waves (destructive interference) | On-device neural network source separation |
| Best Performance | High-frequency clatter and sudden sharp claps | Continuous low-frequency drones (jet engines, fans) | Targeted voices, sirens, or chosen ambient elements |
| Speech Handling | Muffles speech indistinctly | Suppresses steady background speech poorly | Isolates individual voices while muting others |
| Situational Awareness | Blind; blocks critical warning sounds | Artificial; transparency mode lets in all noise | Intelligent; automatically passes safety alerts |
| Computing Demands | Zero power or processing required | Minimal battery impact with dedicated analog/DSP circuits | High; requires dedicated neural processing hardware |
Semantic hearing treats sounds as distinct digital objects rather than a single continuous wave. You gain software-level control over reality's volume mixer.
The 8-Millisecond Race: Beating the Acoustic Echo
Speed is the hardest barrier in acoustic augmented reality. When sound enters your ear canal directly past the silicone seal, your brain registers it almost instantly.
If your earbud's microphone picks up that same sound, processes it through an AI model, and plays it back more than 8 to 10 milliseconds later, your brain perceives a distracting echo or a hollow sound known as a comb filter effect. The entire neural pipeline must complete its work in less time than it takes an insect to flap its wings once.
Hardware engineers achieve this sub-8-millisecond speed through extreme model quantization—compressing hefty neural networks so they perform math using simple 8-bit integers rather than heavy floating-point numbers. To visualize how data pipelines manage strict real-time thresholds, check out our Interactive Engineering Simulations.
Debunking the Myths: EQ Misconceptions and Privacy
A common misconception is that selective hearing is just an automatic equalizer (EQ) preset. An equalizer only boosts or cuts fixed frequency bands, like bass or treble.
If your coworker and the office espresso machine produce sound in the exact same 1,000 Hertz band, an EQ cuts both equally. Neural sound separation separates them because it recognizes the structural signature of human speech versus grinding metal and steam.
Another persistent concern centers on privacy. Many assume that because these earbuds use AI to listen to conversations, they must be recording your day and uploading it to tech giants.
In reality, the processing loop occurs inside a volatile memory buffer that is rewritten thousands of times per second. The earbud's neural chip functions like an analog lens on a pair of glasses: it bends and refines the incoming waves, but keeps no record of what passes through.
Acoustic AR in the Real World: The Construction Site Test
Consider Elena, a civil engineer managing a noisy subway expansion project. Heavy diesel engines idle nearby, concrete saws screech, and workers shout updates across the platform.
With conventional ear protection, Elena faces a dangerous trade-off: she can either protect her hearing and risk missing critical safety callouts, or pull out an earplug and expose her eardrums to permanent acoustic damage.
Wearing neural-filtering earbuds, Elena configures her audio profile to suppress industrial tool noise by 30 decibels while keeping the 300-to-3,000 Hertz speech band open for nearby team members. When an emergency warning horn sounds at a distinct 800 Hertz pattern, the earbud recognizes the safety-critical sound profile and immediately routes it through at full volume. Elena gains clear communication, guaranteed hearing protection, and complete safety awareness simultaneously.
Frequently Asked Questions (FAQ)
Do AI-powered selective hearing earbuds drain the battery much faster?
Yes, running neural networks on an earbud chip consumes significantly more power than standard audio playback. While standard active noise-canceling earbuds often run for six to eight hours per charge, first-generation selective hearing prototypes typically operate for two to four hours. As chip manufacturers develop smaller, more efficient neural processing units built specifically for audio, battery life will steadily approach all-day performance.
Will I notice an unnatural delay or echo when someone speaks?
You will not notice an echo if the processing delay remains below 8 to 10 milliseconds. Human brains easily fuse two identical sounds together when they arrive within this narrow window. Early prototypes occasionally introduced a slight robotic timbre or comb-filtering effect, but modern edge-AI chips process and deliver the isolated audio stream fast enough to feel completely natural.
Can my current wireless earbuds get this feature through a software update?
No, existing mainstream earbuds lack the specialized neural processing hardware required for this capability. Traditional earbuds rely on low-power digital signal processors designed exclusively for basic equalization and simple wave inversion. Running deep neural networks requires dedicated neural accelerators and high-speed memory architectures that cannot simply be added via an over-the-air firmware update.
How do AI earbuds compare to medical hearing aids?
Medical hearing aids are regulated medical devices designed to compensate for specific patterns of biological hearing loss. AI earbuds, while increasingly sophisticated, are consumer hearables primarily built for situational enhancement and comfort. However, the boundary between these two categories is blurring rapidly as major consumer brands gain clinical clearance to offer self-fitting hearing aid modes inside everyday earbuds.
Can these earbuds tune out specific people on command?
Yes, this capability is already functional in controlled settings. By having you look at a speaker for a few seconds or enroll their voice through an app, the neural model registers that person's unique vocal signature. Once enrolled, the earbud locks onto that voice profile, keeping it clear while actively attenuating other voices speaking nearby at similar volume levels.