 Echo Support / SRE • • 1,213 words • 7 min read
Anatomy of a Retry Storm: How One Simple Click Melts Down Servers
Discover how a minor server hiccup turns into a catastrophic meltdown. Unpack retry storm dynamics, thundering herd crises, and clever jitter fixes.
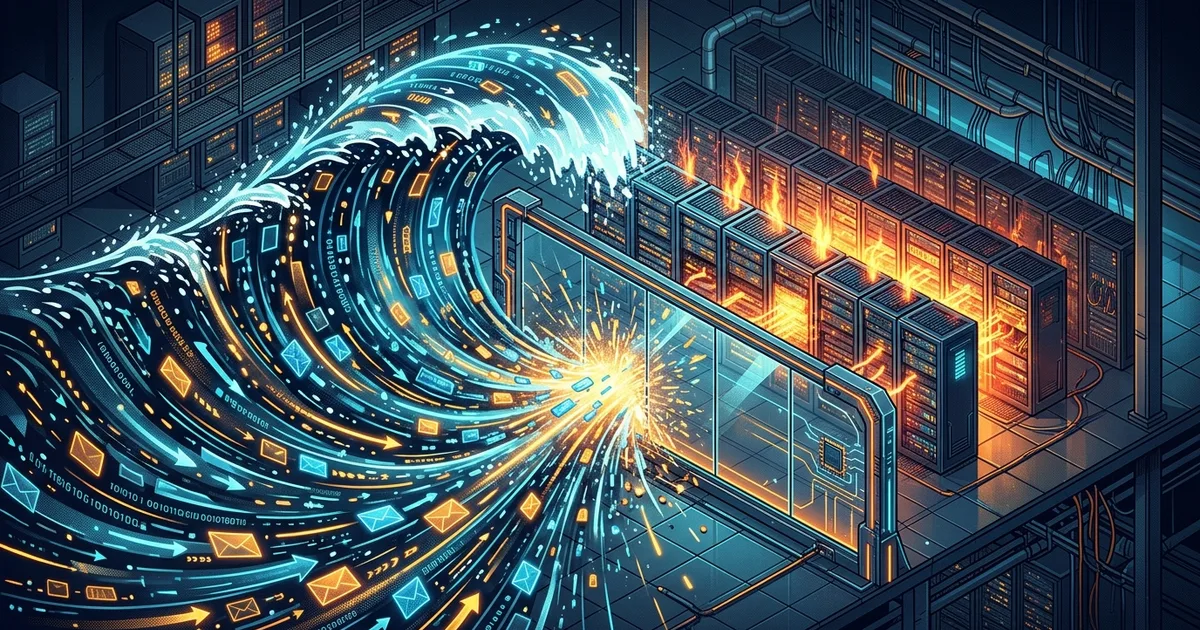
TL;DR (Direct Answer): Retry storm happens when broken server causes thousands of apps to send duplicate requests at same moment. Overloaded backend drowns under massive wave of automated attempts instead of recovering. Single delayed click cascades into total system failure. Recovery requires hard backoff, random delays, and automatic circuit breakers.
Broken Bus Door: How Small Delays Break Big Systems
Imagine crowded morning bus. Bus stops. Pneumatic door jams for two seconds. Passengers inside want exit; crowd outside wants entrance. Instead of waiting, people push door harder. Extra pressure bends metal track. Door now jams permanently. Bus goes out of service.
Digital servers act like this bus door. When web server experiences tiny lag spike, client applications do not wait quietly. Mobile phones and browsers immediately assume request vanished. Software hits server again, twice as hard. Minor hiccup becomes total stoppage.
Test scenarios like this on AI Playground show how pressure turns small glitches fatal. Systems do not die from original error. Systems die from panicked reaction of connected clients.
Crisis Loop: Step-by-Step Anatomy of Meltdown
Meltdown follows predictable positive feedback loop. Positive feedback sounds helpful, but in reliability engineering, term means runaway destruction.
First, backend database slows down under brief query spike. Server response time jumps from twenty milliseconds to five seconds. Clients experience connection timeout.
Second, client software reacts automatically. Instead of failing once, each client issues three immediate retries. Traffic volume quadruples within seconds.
Third, server request queues overflow memory buffers. CPU cores waste all cycles switching between dead connections. Useful work drops to zero.
Fourth, cascading failure spreads to surrounding microservices. Auth service falls; payment gateway follows; cache layers exhaust sockets. Every retry amplifies original load until operator pulls plug.
Comparing Retry Strategies: Smart Backoff vs Blind Retries
Engineers use three primary strategies for failed requests. Simple strategy retries immediately at fixed intervals. Better approach increases delay exponentially. Best approach adds random variation called jitter.
Jitter spreads incoming traffic across time window. Without jitter, retrying clients synchronize into destructive waves like marching army collapsing suspension bridge.
| Strategy | How Delay Works | Impact on Hurt Server | Verdict |
|---|---|---|---|
| Immediate Retry | Zero delay between attempts | Multiplies load instantly; kills backend | Dangerous |
| Fixed Interval | Wait set time like two seconds | Forms rhythmic stampede waves | High Risk |
| Exponential Backoff | Wait doubles each failure: 1s, 2s, 4s | Reduces load, but clients stay synchronized | Partial Fix |
| Exponential + Full Jitter | Exponential delay multiplied by random value | Breaks synchronization; smooths traffic spikes | Recommended Standard |
Circuit Breakers and Jitter: Stopping Herd at Gate
Software needs automated trip switches, identical to electrical circuit breakers in home wiring. When error rates exceed safe threshold, breaker trips open. All outgoing requests fail fast instantly without touching struggling network.
[Client Request]
       │
 [Breaker Open?] ──YES──> [Fail Fast (No Network Call)]
       │ NO
[Send HTTP Request]
       │
[Server Fails?] ──YES──> [Count Error; Trip Breaker if Max Exceeded]
       │ NO
  [Success]
Diagram shows circuit breaker preventing doomed requests from leaving client device.
import random, time

def call_with_retry(fn, max_tries=3, base=1.0):
    # ponytail: basic backoff with full jitter; upgrade to shared breaker when error rate spikes
    for attempt in range(max_tries):
        try:
            return fn()
        except Exception:
            if attempt == max_tries - 1:
                raise
            time.sleep(random.uniform(0, base * (2 ** attempt)))
call_with_retry() → skipped: shared circuit state, add when thread pool needs global tripwire.
Code implements exponential backoff with full jitter using native Python stdlib. Explore live traffic curves using Interactive Engineering Simulations to see load reduction firsthand.
Dangerous Myths: Why Fast Retries Hurt Users
Two widespread misconceptions destroy web platforms daily. First myth claims aggressive retries create smooth user experience. Product managers often demand immediate retries so users never see errors. Reality proves opposite. When server suffers temporary CPU saturation, immediate retries convert temporary hiccup into permanent outage.
Second myth assumes infinite timeouts protect transactions. Giving requests sixty-second timeouts locks server threads open. Worker pools starve. Threads sit idle waiting for dead sockets while fresh requests get rejected.
True resilience accepts defeat early. Failing fast saves system capacity for next user.
War Story: Tiny Router Glitch Triggers Multi-Hour Banking Crash
Major retail bank suffered complete digital blackout on peak payday morning. Incident started with minor sub-second packet drop on internal database switch. Switch recovered within three hundred milliseconds.
Disaster followed immediately. Half million mobile banking applications received network timeout error. Client app code contained hidden flaw: automatic immediate retry without delay or count limit.
Within four seconds, bank ingress gateways received thirty times normal peak traffic. Database thread pool exhausted instantly. Health checks timed out. Kubernetes controllers thought every pod was dead and killed working servers.
Engineers spent four hours reviving systems. Fresh instances died instantly upon launch because mobile apps kept pounding endpoint. Engineers finally stopped storm by blocking all mobile app traffic at edge Cloudflare layer, warming caches, and reopening traffic in five percent increments.
Frequently Asked Questions (FAQ)
What happens when user spams refresh button during outage?
Pressing refresh button restarts entire browser request cycle. Old HTTP connection gets abandoned on client side, but backend server often keeps processing original database query until completion. Each new refresh stacks brand-new work on top of stalled jobs. Multiple refreshes turn single user into accidental denial-of-service attack against struggling platform. Browser caching and edge rate limiting protect backend by ignoring rapid duplicate clicks.
What is jitter and why is it necessary?
Jitter introduces deliberate randomness into retry delay intervals. When hundreds of client applications fail simultaneously, basic exponential backoff causes all devices to retry at exact same second. This produces destructive traffic waves called thundering herds. Adding random noise between zero and maximum backoff window disperses incoming attempts evenly across timeline. Server processes smooth stream of requests instead of drowning under synchronized spikes.
When does circuit breaker open and close?
Circuit breaker monitors failure percentage over sliding time window. When error rate crosses configured threshold, breaker transitions to open state. Open breaker intercepts incoming calls, failing them immediately without making network calls. After preset cooldown period, breaker enters half-open state. It lets small trial batch of requests reach server. If trial succeeds, breaker closes, resuming normal operation. If trial fails, breaker stays open.
How does retry storm differ from cache stampede?
Retry storm occurs when clients repeatedly hammer failing service after timeouts or network errors, compounding server CPU strain. Cache stampede, or thundering herd, occurs when heavily read cache key expires suddenly. Thousands of simultaneous requests bypass cache layer at once, hitting underlying database simultaneously to rebuild missing key. While triggers differ, both phenomena create positive feedback loops that exhaust server resources and require request coalescing solutions.
How does service protect itself from aggressive client retries?
Services protect themselves using layered defensive mechanisms. Edge gateways enforce strict rate limiting per IP address or user account. When capacity drops, load balancers shed excess load by returning HTTP status code 429 Too Many Requests or 503 Service Unavailable, accompanied by Retry-After header. Internally, services implement prioritized queues and token bucket limiters, dropping non-critical background jobs to preserve core transaction processing capacity.